AI Reliability Engineering

Your LLM feature is live. Can you tell if it's getting better or worse?

Keelsworth makes GenAI systems dependable in production: evaluation datasets, LLM judges calibrated against human review, guardrails that stop bad output before users see it, and orchestration that recovers instead of failing. For new builds and for systems already serving users.

Remote, working US, UK and Gulf hours.

Where GenAI systems slip

The demo worked. Production is a different job.

01

A prompt or model change ships, and nobody can say whether quality went up or down.

02

Wrong or off-policy output reaches users before anyone on the team notices.

03

Agents and pipelines fail halfway through and need a person to restart them.

04

Every new feature or model upgrade means re-testing everything by hand.

What we put in place

  • Versioned evaluation datasets built from real traffic and reviewer feedback
  • LLM-as-judge grading, calibrated against human review
  • Guardrails and schema-enforced outputs
  • CI regression gates that block bad releases
  • Tracing and observability, with Langfuse or your stack
  • Orchestration with validation, retries and repair loops

Services

Start with an audit. Build what it finds.

Fixed-scope work with clear deliverables. Most engagements start with the audit; the build or ongoing support is proposed at the readout, not before.

Start here

AI Reliability Audit

2 weeks · fixed price

from $3,000

  • Map failure modes across prompts, models and pipelines
  • Review eval coverage, validators, observability and release process
  • Prioritised fix plan plus a starter regression dataset

Works for new builds and for systems already in production.

Evaluation & guardrails build

6–10 weeks

from $12,000

  • Eval datasets versioned from your real traffic
  • LLM judges calibrated against human labels
  • CI gates that catch regressions before release

Usually follows the audit, scoped from what it finds.

Fractional AI engineering lead

1–2 days a week

from $5,000 / month

  • Own reliability and AI architecture decisions
  • Coach engineers on evals, guardrails and AI coding tools
  • A steady hand through model upgrades and new features

For teams shipping AI features without an AI lead in-house.

Also available: AI-enablement programmes for engineering teams adopting AI coding tools.

Recent work

Production LLM pipelines, made dependable.

Senior AI Engineer, LearnWith.AI (Trilogy group, US), 2025–2026

  1. 01Helped take AI course generation from prompt-assisted authoring to a near-fully automated pipeline in 18 months, on a 12–20 person team.
  2. 02Designed generators and validators with schema-enforced outputs and guardrails, so invalid content never reached a learner.
  3. 03Built regression testing for LLM systems: Langfuse datasets as test cases, LLM-as-judge evaluation catching regressions before release.
  4. 04Sole engineer on a feedback-to-ground-truth pipeline (11 weeks, 141 PRs, 5 ADRs) that turns reviewer verdicts into versioned evaluation datasets.
  5. 05Built a 25+ generator library rendering figures from LLM output, and filed 21 root-caused production bug reports.

Before that

Nine years as CTO

Co-founder and CTO of TutorBees.net, a multi-country tutoring marketplace on AWS: product, engineering, infrastructure and team.

Five systems, one programme

Led delivery of a mental-health support programme: three mobile apps, an LMS and a registration portal, integrated into one working system.

Gamified recruitment

Delivered a gamified recruitment platform for a client as co-founder of TechHive, a web, mobile and conversational-AI studio.

Rubab Fatima

About

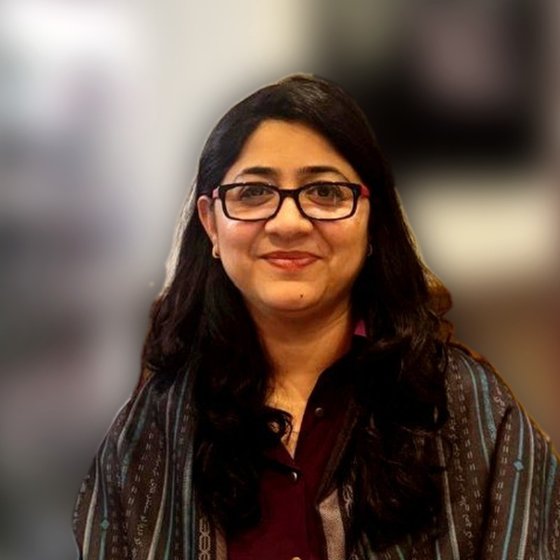
Rubab Fatima, founder

Keelsworth is my AI reliability engineering practice. I've spent 15+ years building and leading software delivery: nine as a CTO, then hands-on GenAI engineering for a US EdTech company, where my job was making LLM pipelines trustworthy enough to run without a human in the loop. Earlier, enterprise integration and BI for US clients at Techlogix, and engineering training at NetSol. I translate between leadership, product and engineers.

Python · FastAPI · Pydantic · Langfuse · AWS Lambda & Step Functions · Bedrock · OpenAI and Anthropic models
Next step

Bring one real example.

A 30-minute call about an LLM feature you're building or running: what's breaking, how you'd know if a change made it better or worse, and what it would take to ship with confidence. Bring a failing output or a trace if you have one.